
model_id stringlengths 8 65 | model_card stringlengths 0 15.7k | model_labels listlengths |
|---|---|---|
microsoft/kosmos-2-patch14-224 | # Kosmos-2: Grounding Multimodal Large Language Models to the World
<a href="https://huggingface.co/microsoft/kosmos-2-patch14-224/resolve/main/annotated_snowman.jpg" target="_blank"><figure><img src="https://huggingface.co/microsoft/kosmos-2-patch14-224/resolve/main/annotated_snowman.jpg" width="384"><figcaption><b>[... | null |
merve/blip2-opt-6.7b |
# BLIP-2, OPT-6.7b, pre-trained only
BLIP-2 model, leveraging [OPT-6.7b](https://huggingface.co/facebook/opt-6.7b) (a large language model with 6.7 billion parameters).
It was introduced in the paper [BLIP-2: Bootstrapping Language-Image Pre-training with Frozen Image Encoders and Large Language Models](https://arxiv... | null |
dblasko/blip-dalle3-img2prompt |
# DALL·E 3 Image prompt reverse-engineering
Pre-trained image-captioning model BLIP fine-tuned on a mixture of `laion/dalle-3-dataset` and semi-automatically gathered `(image, prompt)` data from DALLE·E 3.
It takes a generated image as an input and outputs a potential prompt to generate such an image, which can then... | null |
merve/blip2-flan-t5-xxl |
# BLIP-2, Flan T5-xxl, pre-trained only
BLIP-2 model, leveraging [Flan T5-xxl](https://huggingface.co/google/flan-t5-xxl) (a large language model).
It was introduced in the paper [BLIP-2: Bootstrapping Language-Image Pre-training with Frozen Image Encoders and Large Language Models](https://arxiv.org/abs/2301.12597) ... | null |
smdesai/blip2-flan-t5-xxl |
# BLIP-2, Flan T5-xxl, pre-trained only
BLIP-2 model, leveraging [Flan T5-xxl](https://huggingface.co/google/flan-t5-xxl) (a large language model).
It was introduced in the paper [BLIP-2: Bootstrapping Language-Image Pre-training with Frozen Image Encoders and Large Language Models](https://arxiv.org/abs/2301.12597) ... | null |
Ayansk11/Image_Caption_using_ViT_GPT2 |
# The Illustrated Image Captioning using transformers
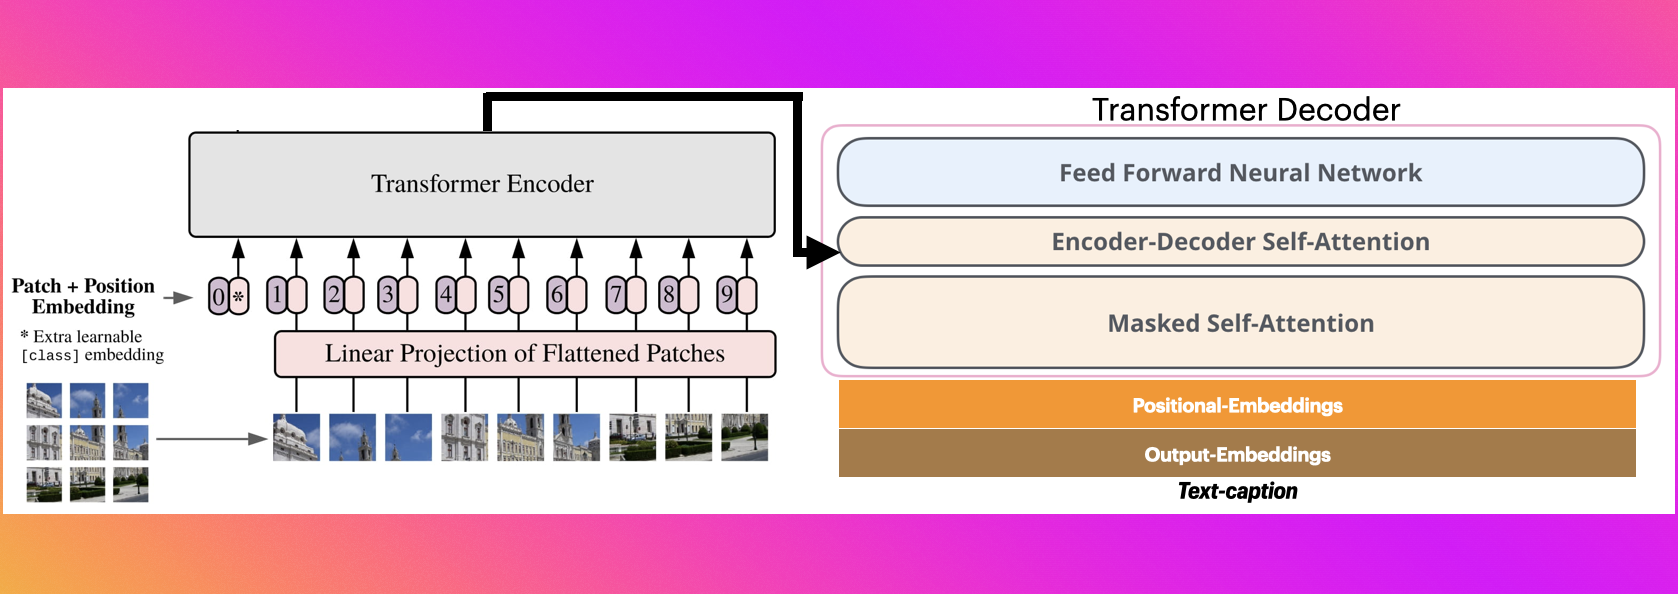
# Sample running code
```python
from transformers import VisionEncoderDecoderModel, ViTImageProcessor, AutoTokenizer
import torch
from PIL import Image
model = VisionEncoderDecoderMode... | null |
mrvero/BT-Image-Captioning-Large |
# BLIP: Bootstrapping Language-Image Pre-training for Unified Vision-Language Understanding and Generation
Model card for image captioning pretrained on COCO dataset - base architecture (with ViT large backbone).
| 
Volcano employs a single LMM to generate initial responses, fe... | null |
kaist-ai/volcano-13b | ## Links for Reference
- **Repository: https://github.com/kaistAI/Volcano**
- **Paper: https://arxiv.org/abs/2311.07362**
# Overview

Volcano employs a single LMM to generate initial responses, fe... | null |
shadowlilac/visor |
# Visor - Natural language Anime Tagging
Visor is a natural-language-based image tagging model based on the BLIP model architecture.
Potential Use cases can be to caption anime images for training diffusion models | null |
kpyu/eilev-blip2-opt-2.7b | # Model Card for EILEV BLIP-2-OPT-2.7B

[Salesforce/blip2-opt-2.7b](https://huggingface.co/Salesforce/blip2-opt-2.7b) trained using [EILeV](https://github.com/yukw777/EILEV), a novel training method that can elicit in-context learning in vision-language models (VLMs) for videos without requiring ... | null |
kpyu/eilev-blip2-flan-t5-xl | # Model Card for EILEV BLIP-2-Flan-T5-xl

[Salesforce/blip2-flan-t5-xl](https://huggingface.co/Salesforce/blip2-flan-t5-xl) trained using [EILeV](https://github.com/yukw777/EILEV), a novel training method that can elicit in-context learning in vision-language models (VLMs) for videos without requ... | null |
toshi456/llava-jp-1.3b-v1.0 |
# LLaVA-JP Model Card
## Model detail
**Model type:**
LLaVA-JP is a vision-language model that can converse about input images.<br>
This model was trained by fine-tuning [llm-jp/llm-jp-1.3b-v1.0](https://huggingface.co/llm-jp/llm-jp-1.3b-v1.0) using [LLaVA](https://llava-vl.github.io/) method.
**Training:**
This... | null |
Vidensogende/image-captioning-with-blip |
# BLIP: Bootstrapping Language-Image Pre-training for Unified Vision-Language Understanding and Generation
Model card for image captioning pretrained on COCO dataset - base architecture (with ViT large backbone).
|  (a large language model).
It was introduced in the paper [BLIP-2: Bootstrapping Language-Image Pre-training with Frozen Image Encoders and Large Language Models](https://arxiv.org/abs/2301.12597) ... | null |
unum-cloud/uform-gen | <Gallery />
<h1 align="center">UForm</h1>
<h3 align="center">
Pocket-Sized Multimodal AI<br/>
For Content Understanding and Generation<br/>
</h3>
## Description
UForm-Gen is a small generative vision-language model primarily designed for Image Captioning and Visual Question Answering. The model consists of two part... | null |
unum-cloud/uform-gen-chat |
<h1 align="center">UForm</h1>
<h3 align="center">
Pocket-Sized Multimodal AI<br/>
For Content Understanding and Generation<br/>
</h3>
## Description
UForm-Gen is a small generative vision-language model primarily designed for Image Captioning and Visual Question Answering. The model consists of two parts:
1. [UFo... | null |
mrSoul7766/git-base-instagram-cap |
<!-- This model card has been generated automatically according to the information the Trainer had access to. You
should probably proofread and complete it, then remove this comment. -->
# git-base-instagram-cap
This model is a fine-tuned version of [microsoft/git-base](https://huggingface.co/microsoft/git-base) on ... | null |
4bit/uform-gen | <Gallery />
<h1 align="center">UForm</h1>
<h3 align="center">
Pocket-Sized Multimodal AI<br/>
For Content Understanding and Generation<br/>
</h3>
## Description
UForm-Gen is a small generative vision-language model primarily designed for Image Captioning and Visual Question Answering. The model consists of two part... | null |
adasdimchom/blip2-opt-6.7b-coco |
# BLIP-2, OPT-6.7b, fine-tuned on COCO
BLIP-2 model, leveraging [OPT-6.7b](https://huggingface.co/facebook/opt-6.7b) (a large language model with 6.7 billion parameters).
It was introduced in the paper [BLIP-2: Bootstrapping Language-Image Pre-training with Frozen Image Encoders and Large Language Models](https://arx... | null |
adasdimchom/blip2-opt-2.7b-coco |
# BLIP-2, OPT-2.7b, fine-tuned on COCO
BLIP-2 model, leveraging [OPT-2.7b](https://huggingface.co/facebook/opt-2.7b) (a large language model with 2.7 billion parameters).
It was introduced in the paper [BLIP-2: Bootstrapping Language-Image Pre-training with Frozen Image Encoders and Large Language Models](https://arx... | null |
adasdimchom/blip-image-captioning-large |
# BLIP: Bootstrapping Language-Image Pre-training for Unified Vision-Language Understanding and Generation
Model card for image captioning pretrained on COCO dataset - base architecture (with ViT large backbone).
| .
| .
|  using [LLaVA](https://llava-vl.github.io/) method and [google/siglip-so... | null |
unum-cloud/uform-gen2-qwen-500m |
<h1 align="center">UForm</h1>
<h3 align="center">
Pocket-Sized Multimodal AI<br/>
For Content Understanding and Generation<br/>
</h3>
## Description
UForm-Gen is a small generative vision-language model primarily designed for Image Captioning and Visual Question Answering. The model consists of two parts:
1. CLIP... | null |
turing-motors/heron-chat-blip-ja-stablelm-base-7b-v1 | # Heron BLIP Japanese StableLM Base 7B v1
## Model Details
Heron BLIP Japanese StableLM Base 7B is a vision-language model that can converse about input images.<br>
This model was trained using [the heron library](https://github.com/turingmotors/heron). Please refer to the code for details.
## Usage
Follow [the in... | null |
benferns/instructblip-flan-t5-xl_8bit_nf4 |
Quantization with [bitsandbytes](https://github.com/TimDettmers/bitsandbytes)
_8-bit / nf4 / Safetensors_
-_Mediocre_ 🥱
# InstructBLIP model
InstructBLIP model using [Flan-T5-xl](https://huggingface.co/google/flan-t5-xl) as language model. InstructBLIP was introduced in the paper [InstructBLIP: Towards General... | null |
turing-motors/heron-chat-blip-ja-stablelm-base-7b-v1-llava-620k | # Heron BLIP Japanese StableLM Base 7B llava-620k
## Model Details
Heron BLIP Japanese StableLM Base 7B is a vision-language model that can converse about input images.<br>
This model was trained using [the heron library](https://github.com/turingmotors/heron). Please refer to the code for details.
## Usage
Follow... | null |
orzhan/git-base-minecraft | null | |
ishaangupta293/kosmos-2-patch14-24-dup-ms | # Kosmos-2: Grounding Multimodal Large Language Models to the World
<a href="https://huggingface.co/microsoft/kosmos-2-patch14-224/resolve/main/annotated_snowman.jpg" target="_blank"><figure><img src="https://huggingface.co/microsoft/kosmos-2-patch14-224/resolve/main/annotated_snowman.jpg" width="384"><figcaption><b>[... | null |
advaitadasein/blip2-opt-6.7b |
# BLIP-2, OPT-6.7b, pre-trained only
BLIP-2 model, leveraging [OPT-6.7b](https://huggingface.co/facebook/opt-6.7b) (a large language model with 6.7 billion parameters).
It was introduced in the paper [BLIP-2: Bootstrapping Language-Image Pre-training with Frozen Image Encoders and Large Language Models](https://arxiv... | null |
SRDdev/Nebula | null | |
tarekziade/distilvit |
This model is a variation of https://huggingface.co/nlpconnect/vit-gpt2-image-captioning
- Read the blog post here https://ziade.org/2024/03/17/distilvit-image-captioning-model
- The training code is here: https://github.com/tarekziade/distilvit
Results after after 3 epochs (and ~45 hours of training)
- eval_loss: ... | null |
tarekziade/deit-tiny-distilgpt2 |
Variation of https://huggingface.co/tarekziade/distilvit
Trained on 270k images from Flickr10k and COCO.
Training source code: https://github.com/tarekziade/distilvit
Results:
- eval_loss: 0.2305169701576233
- eval_rouge1: 39.511
- eval_rouge2: 14.7798
- eval_rougeL: 35.9476
- eval_rougeLsum: 35.9497
- eval_gen_le... | null |
unum-cloud/uform-gen2-dpo | <img src="Captions.jpg">
## Description
UForm-Gen2-dpo is a small generative vision-language model alined for Image Captioning and Visual Question Answering
on preference datasets VLFeedback and LLaVA-Human-Preference-10K using Direct Preference Optimization (DPO).
The model consists of two parts:
1. CLIP-like V... | null |
turing-motors/heron-chat-git-ja-stablelm-base-7b-v1 | # Heron GIT Japanese StableLM Base 7B
## Model Details
Heron GIT Japanese StableLM Base 7B is a vision-language model that can converse about input images.<br>
This model was trained using [the heron library](https://github.com/turingmotors/heron). Please refer to the code for details.
## Usage
Follow [the install... | null |
sashakunitsyn/vlrm-blip2-opt-2.7b | # VLRM
This repository contains the weights of BLIP-2 OPT-2.7B model fine-tuned by reinforcement learning method introduced in the paper [VLRM: Vision-Language Models act as
Reward Models for Image Captioning](https://arxiv.org/abs/2404.01911).
The RL-tuned model is able to generate longer and more comprehensive descr... | null |
Wang9738/blip-image-captioning-base-Opticalvehicle-finetuned |
# BLIP: Bootstrapping Language-Image Pre-training for Unified Vision-Language Understanding and Generation
Model card for image captioning pretrained on COCO dataset - base architecture (with ViT base backbone) - and fine-tuned on
[football dataset](https://huggingface.co/datasets/ybelkada/football-dataset).
Google ... | null |
atasoglu/vit-base-patch16-224-turkish-gpt2 | # vit-base-patch16-224-turkish-gpt2
This vision encoder-decoder model utilizes the [google/vit-base-patch16-224](https://huggingface.co/google/vit-base-patch16-224) as the encoder and [ytu-ce-cosmos/turkish-gpt2](https://huggingface.co/ytu-ce-cosmos/turkish-gpt2) as the decoder, and it has been fine-tuned on the [flic... | null |
atasoglu/vit-base-patch16-224-turkish-gpt2-medium |
# vit-base-patch16-224-turkish-gpt2-medium
This vision encoder-decoder model utilizes the [google/vit-base-patch16-224](https://huggingface.co/google/vit-base-patch16-224) as the encoder and [ytu-ce-cosmos/turkish-gpt2-medium](https://huggingface.co/ytu-ce-cosmos/turkish-gpt2-medium) as the decoder, and it has been f... | null |
aisak-ai/aisak-visual | # AISAK-Visual
## Overview:
AISAK-Visual, part of the AISAK system, is a pretrained model for image captioning based on the BLIP framework. Altered by the AISAK team from the https://huggingface.co/Salesforce/blip-image-captioning-large model, this model utilizes a ViT base backbone for unified vision-language unders... | null |
abhijit2111/Pic2Story |
This isi the BLIP salesforce large image captioning model with small adjustments to the paramaters on the back end for testing - note in particular the length of reply is increased.
# BLIP: Bootstrapping Language-Image Pre-training for Unified Vision-Language Understanding and Generation
Model card for image captio... | null |
atasoglu/vit-small-patch16-224-turkish-small-bert-uncased |
# vit-small-patch16-224-turkish-small-bert-uncased
This vision encoder-decoder model utilizes the [WinKawaks/vit-small-patch16-224](https://huggingface.co/WinKawaks/vit-small-patch16-224) as the encoder and [ytu-ce-cosmos/turkish-small-bert-uncased](https://huggingface.co/ytu-ce-cosmos/turkish-small-bert-uncased) as ... | null |
atasoglu/vit-tiny-patch16-224-turkish-small-bert-uncased |
# vit-tiny-patch16-224-turkish-small-bert-uncased
This vision encoder-decoder model utilizes the [WinKawaks/vit-tiny-patch16-224](https://huggingface.co/WinKawaks/vit-tiny-patch16-224) as the encoder and [ytu-ce-cosmos/turkish-small-bert-uncased](https://huggingface.co/ytu-ce-cosmos/turkish-small-bert-uncased) as the... | null |
unography/blip-large-long-cap |
# LongCap: Finetuned [BLIP](https://huggingface.co/Salesforce/blip-image-captioning-large) for generating long captions of images, suitable for prompts for text-to-image generation and captioning text-to-image datasets
## Usage
You can use this model for conditional and un-conditional image captioning
### Using th... | null |
toshi456/llava-jp-1.3b-v1.1 |
# LLaVA-JP Model Card
## Model detail
**Model type:**
LLaVA-JP is a vision-language model that can converse about input images.<br>
This model is an LVLM model trained using [google/siglip-so400m-patch14-384](https://huggingface.co/google/siglip-so400m-patch14-384) as the image encoder and [llm-jp/llm-jp-1.3b-v1.0]... | null |
toshi456/llava-jp-1.3b-v1.0-620k |
# LLaVA-JP Model Card
## Model detail
**Model type:**
LLaVA-JP is a vision-language model that can converse about input images.<br>
This model was trained by fine-tuning [llm-jp/llm-jp-1.3b-v1.0](https://huggingface.co/llm-jp/llm-jp-1.3b-v1.0) using [LLaVA](https://llava-vl.github.io/) method and [google/siglip-so... | null |
unography/blip-large-long-cap-sam-llava |
# LongCap: Finetuned [BLIP](https://huggingface.co/Salesforce/blip-image-captioning-large) for generating long captions of images, suitable for prompts for text-to-image generation and captioning text-to-image datasets
## Usage
You can use this model for conditional and un-conditional image captioning
### Using th... | null |
Revrse/icon-captioning-model |
```python
import requests
from PIL import Image
from transformers import BlipProcessor, BlipForConditionalGeneration
processor = BlipProcessor.from_pretrained("Revrse/icon-captioning-model")
model = BlipForConditionalGeneration.from_pretrained("Revrse/icon-captioning-model")
img_url = 'https://storage.googleapis.com/s... | null |
unography/blip-long-cap |
# LongCap: Finetuned [BLIP](https://huggingface.co/Salesforce/blip-image-captioning-base) for generating long captions of images, suitable for prompts for text-to-image generation and captioning text-to-image datasets
## Usage
You can use this model for conditional and un-conditional image captioning
### Using the... | null |
toshi456/llava-jp-karasu-1.1b-v1.0-620k |
# LLaVA-JP Model Card
## Model detail
**Model type:**
LLaVA-JP is a vision-language model that can converse about input images.<br>
This model was trained by fine-tuning [lightblue/karasu-1.1B](https://huggingface.co/lightblue/karasu-1.1B) using [LLaVA](https://llava-vl.github.io/) method and [google/siglip-so400m... | null |
toshi456/chat-vector-llava-v1.5-7b-ja |
# Chat-Vector-LLaVA-v1.5-7b-JA Model Card
## Model detail
**Model type:**
Chat-Vector-LLaVA-v1.5-7b-JA is a vision-language model that can converse about input images in Japanese.<br>
This model was created by adding and subtracting the weights of the [llava-v1.5-7b](https://huggingface.co/liuhaotian/llava-v1.5-7b), [... | null |
evlinzxxx/my_model_ViTB-16 |
# Sample running code
```python
from transformers import VisionEncoderDecoderModel, ViTImageProcessor, GPT2Tokenizer
import torch
from PIL import Image
model = VisionEncoderDecoderModel.from_pretrained("evlinzxxx/my_model_ViTB-16")
feature_extractor = ViTImageProcessor.from_pretrained("evlinzxxx/my_model_ViTB-16")
tok... | null |
anonymoussubmission2024/vlrm-blip2-opt-2.7b | # VLRM
This repository contains the weights of BLIP-2 OPT-2.7B model fine-tuned by reinforcement learning method introduced in the paper VLRM: Vision-Language Models Act as
Reward Models for Image Captioning.
The RL-tuned model is able to generate longer and more comprehensive descriptions with zero computational over... | null |
aayushgs/Salesforce-blip-image-captioning-large-custom-handler |
# BLIP: Bootstrapping Language-Image Pre-training for Unified Vision-Language Understanding and Generation
Model card for image captioning pretrained on COCO dataset - base architecture (with ViT large backbone).
| 
feature_extractor = ViTImageProcessor.from_pretrained("evlinzxxx/best_model_ViTB1... | null |
dxkrnn/blipball |
# BLIP: Bootstrapping Language-Image Pre-training for Unified Vision-Language Understanding and Generation
Model card for image captioning pretrained on COCO dataset - base architecture (with ViT base backbone) - and fine-tuned on
[football dataset](https://huggingface.co/datasets/ybelkada/football-dataset).
Google ... | null |
pltnhan311/image-captioning_vit-gpt2 |
# nlpconnect/vit-gpt2-image-captioning
This is an image captioning model trained by @ydshieh in [flax ](https://github.com/huggingface/transformers/tree/main/examples/flax/image-captioning) this is pytorch version of [this](https://huggingface.co/ydshieh/vit-gpt2-coco-en-ckpts).
# The Illustrated Image Captio... | null |
pltnhan311/image-captioning-vit-gpt2-flick8k | null | |
shinyice/chatvector-llava-v1.5-plus-houou-v3-7b |
# Chatvector-llava-v1.5-plus-Houou-v3-7b Model Card
# Model Details
※好奇心から生まれたモデルです。精度は保証できませんが、v1.6を用いたものよりは良い気がしています。<br>
chatvector-llava-v1.5-plus-houou-v3-7bは日本語で画像を説明することが可能なVLMです。<br>
[Chat Vector](https://arxiv.org/abs/2310.04799)の手法に影響を受けています。
このモデルはChat Vectorを参考に[llava-v1.5-7b](https://huggingface.co/liuhao... | null |
toshi456/ConvLLaVA-JP-1.3b-768 |
# ConvLLaVA-JP Model Card
## Model detail
**Model type:**
ConvLLaVA-JP is a vision-language model that can converse about input images.<br>
This model is an LVLM model trained using [laion/CLIP-convnext_large_d_320.laion2B-s29B-b131K-ft](https://huggingface.co/laion/CLIP-convnext_large_d_320.laion2B-s29B-b131K-ft) ... | null |
pniedziela96/blip-image-captioning-base-pokemon-finetune |
# Model Card for Model ID
<!-- Provide a quick summary of what the model is/does. -->
## Model Details
### Model Description
<!-- Provide a longer summary of what this model is. -->
This is the model card of a 🤗 transformers model that has been pushed on the Hub. This model card has been automatically generate... | null |
toshi456/ConvLLaVA-JP-1.3b-1280 |
# ConvLLaVA-JP Model Card
## Model detail
**Model type:**
ConvLLaVA-JP is a vision-language model that can converse about input images.<br>
This model is an LVLM model trained using [laion/CLIP-convnext_large_d_320.laion2B-s29B-b131K-ft](https://huggingface.co/laion/CLIP-convnext_large_d_320.laion2B-s29B-b131K-ft) ... | null |
tarekziade/vit-base-patch16-224-distilgpt2 |
# distilvit
This model is a work in progress. Fine-tuned version of those base models:
- a VIT model for the image encoder: https://huggingface.co/google/vit-base-patch16-224-in21k
- a Distilled GPT-2 model for the text decoder: https://huggingface.co/distilbert/distilgpt2
This model was trained on:
- Fl... | null |
sooh-j/blip-image-captioning-base |
# BLIP: Bootstrapping Language-Image Pre-training for Unified Vision-Language Understanding and Generation
Model card for image captioning pretrained on COCO dataset - base architecture (with ViT base backbone).
| .
|  on the [FlowerEvolver-dataset](https://huggingface.co/datasets/cristianglezm/FlowerEvolver-Dataset) dataset.
It achieves the following results on the eva... | null |
mo-thecreator/ViT-GPT2-Image_Captioning_model |
<!-- This model card has been generated automatically according to the information the Trainer had access to. You
should probably proofread and complete it, then remove this comment. -->
# ViT-GPT2
This model is a fine-tuned version of [](https://huggingface.co/) on an unknown dataset.
It achieves the following resu... | null |
Srivardhan369/attention_mechanism_369 | null | |
vidi-deshp/clip-gpt2-finetuned |
# Fine-Tuned CLIP-GPT2 Model for Image Captioning
This is a fine-tuned version of CLIP-GPT2 for real-time image captioning to aid the visually impaired.
## Model Details:
- **Base Model:** CLIP ViT-B/32
- **Fine-Tuned On:** VizWiz dataset
- **Format:** SafeTensors
- **Usage:**
```python
from transform... | null |
omarsabri8756/blip-Arabic-flickr-8k |
# BLIP Image Captioning - Arabic (Flickr8k Arabic)
This model is a fine-tuned version of [`Salesforce/blip-image-captioning-large`](https://huggingface.co/Salesforce/blip-image-captioning-large), adapted for **image captioning in Arabic** using the **Flickr8K Arabic dataset**. It takes an input image and generates a r... | null |
gw099/art-describer-5k |
# Art Describer 5K
This model is a fine-tuned version of the BLIP image captioning model, specifically trained to describe artworks. It was trained on 5,000 examples of public domain artwork with their corresponding text descriptions.
## Model Details
- **Base Model**: BLIP (Salesforce/blip-image-captioning-... | null |
hibikigf88/blip-caption-newyorker |
<!-- This model card has been generated automatically according to the information the Trainer had access to. You
should probably proofread and complete it, then remove this comment. -->
# blip-caption-newyorker
This model is a fine-tuned version of [Salesforce/blip-image-captioning-base](https://huggingface.co/Sale... | null |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.